October 4, 2026
Mixture of Agents in Hermes: 4 Models vs 1 on a Real Plan
I ran a mixture of agents review in Hermes against 1 model on my real design plan. Solo called my routing sound. The team found the boundary it missed.
Mixture of agents means asking several models for independent advice, then letting 1 model turn that advice into the answer. I set it up in Hermes and gave it a real job: review the expansion plan for my Hermes World Engine. I gave the same plan to 1 model alone. Solo said my routing was sound. The team found the missing boundary that keeps the workflow from drifting.
That is the video above. Here it is in writing, with the real screens.
The plan under review
The Hermes World Engine is a world that stays the same, with characters brought into it. Aether Falls, Archive Cloister, Crystal Citadel, Gateway Pavilion. The goal is animations that teach Hermes. See it at 0:30.
The plan expands it into 1 optional, routed workflow. The opening question is: what are we building? An image, a character, a world or a storied animation. Every answer takes a different path.
A plan with many paths is where 1 reviewer settles too fast. So I wanted more than 1 opinion.
How mixture of agents works in Hermes
Hermes runs it as a preset: a few advisers and 1 aggregator.
- The advisers get the conversation’s user and assistant text. They do not get the Hermes system prompt, the record of tool calls, or the tools.
- The aggregator gets the full Hermes context, the tools, and the advisers’ outputs. It runs the tools and writes the answer.
- By default the advisers run once per user turn. The aggregator runs every step, so most of the cost lands on its provider.
It is not a majority vote. The aggregator weighs the advice and makes the call. At 2:29.
All of that is from the Nous Research docs on Mixture of Agents. And since Hermes v0.18, each adviser’s answer shows up as its own block, so you can read what each model said.
2 runs failed, then the fix
My first run never finished. 1 adviser’s call failed on a Cloudflare lookup. My best guess is that it went looking for the tools in my plan and hit a security gate. So I gave the review rules: judge the plan, not the tools. At 6:02.
My second run came back saying it had my instructions, but not the design. No advisers were consulted. At 6:49.
It took me about 45 minutes to find the fix. A preset is a model, and you have to select it as your model. At 7:04.
/model budget-review --provider moaselects the preset. Every message after that runs through the team./moaruns 1 prompt through your default preset, then puts your old model back.
The team I ran
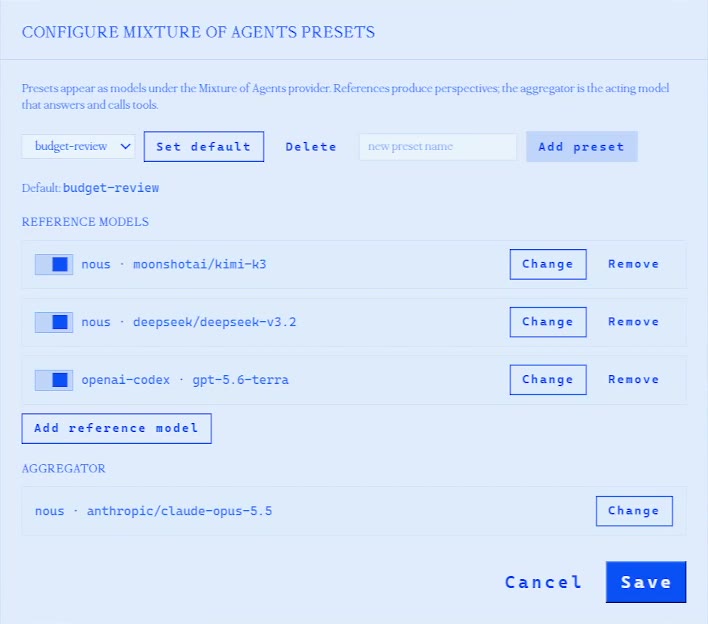
3 advisers: Kimi K3, DeepSeek V3.2, and GPT-5.6 Terra. Claude Opus 5.5 as the aggregator. The single model was GPT-6.1 Sol. At 7:42.
I started with a budget preset picked on cost. Qwen3 235B was listed at $0.09 in and $0.35 out per million tokens. At 4:49. The review that worked ran on the stronger team above.
Where solo failed
Then I pasted both outcomes in and had them compared.
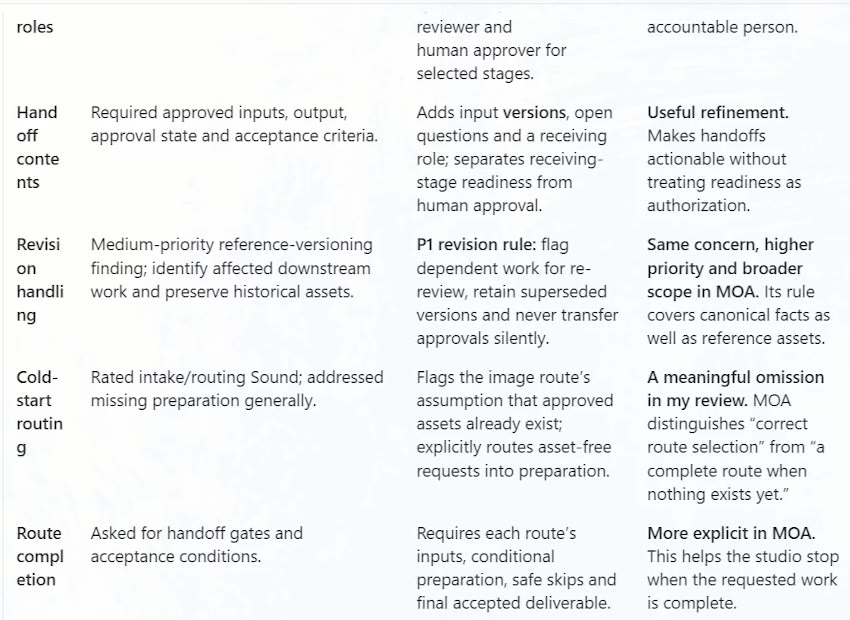
Both agreed at the top. Keep the direction, but define how it operates before building it.
Here is where solo failed. It rated my intake and routing sound. The team flagged that the image route assumes approved assets already exist. The comparison called it “a meaningful omission.” At 8:17.
Route completion was the same story. Solo asked for handoff gates and acceptance conditions. The team required each route’s inputs, safe skips, and the accepted deliverable. That is how the workflow knows it is done.
A workflow without boundaries and rules drifts. At 8:42.
1 thing to know: Sol wrote that comparison. So Sol graded its own review, and still called its miss a meaningful omission.
Which advisers earned their tokens
Opus, as the aggregator, reported that Kimi K3 was the most independent. DeepSeek largely repeated an earlier review. Terra gave qualified findings. That is what the aggregator reported, not something I measured. At 8:55.
I could probably have run DeepSeek and Kimi K3 alone and saved the tokens on Terra. The more you run this, the more you learn what your job needs.
Try it on your own plan
Pick 1 plan you care about. Set up a preset, select it as your model, and give it the plan itself, with rules that say what to judge. Then compare it to 1 model on the same plan.
The plan lives in my ICM workspace, the same folders I walk through in the AI agent memory post. If you are still setting Hermes up, the Hermes page is the ladder.
The 4 strategy files from this build, each ending in a prompt you can run on your own plan, are in my classroom inside Build Market Close. Heads up: that is an affiliate link, and I earn a commission if you join through it. Build Market Close.
Sources
- https://hermes-agent.nousresearch.com/docs/user-guide/features/mixture-of-agents
- https://github.com/NousResearch/hermes-agent/releases/tag/v2026.7.1
Want the folders? The 3 folder start is free and it takes about 20 minutes. Build it.